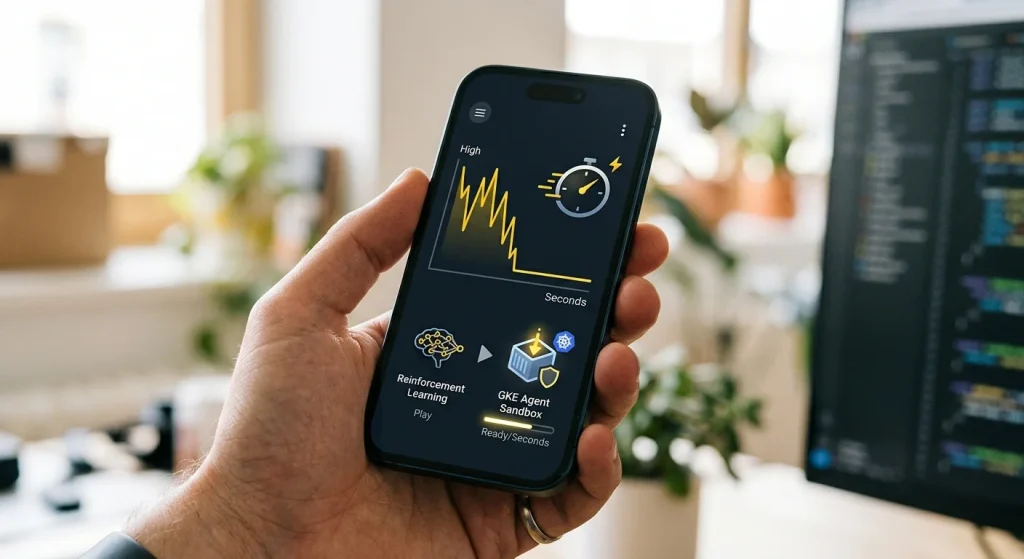
- Google Cloud’s GKE Agent Sandbox cuts sandbox spin-up times from 45-85 seconds to 1-9 seconds, a 10x to 45x improvement in time-to-first-command for agentic RL workloads, according to Google Cloud’s own benchmarks.
- The built-in SandboxWarmPool drops worst-case sandbox wait times from 7.5 minutes to under 10 seconds, keeping GPUs active during large-scale parallel rollouts.
- Mistral AI is running GKE Agent Sandbox in production; the Python SDK integrates with Gymnasium, NVIDIA NeMo Gym and OpenHands, letting research teams configure environments without writing Kubernetes YAML.
Google Cloud launched GKE Agent Sandbox optimized for RL on September 29, 2026, and the headline number is blunt: sandbox spin-up times drop from 45-85 seconds to 1-9 seconds, according to the company. Mistral AI is already running it in production. For teams burning GPU budget on CPU sandbox cold-starts, that gap is where the money goes.
Kubernetes vs. Agentic RL
Agentic reinforcement learning is nothing like stateless model inference. Agents run continuously, maintain context, call external tools and execute untrusted code across multiple turns. That profile demands strong isolation, fast lifecycle management and stable networking, all at once, across potentially thousands of concurrent environments.
Standard Kubernetes falls short here. Basic containerization leaves ingress and egress open, lacks policy enforcement and does little to contain a runaway agent. Proper agent sandboxing needs isolated credential and tool-call boundaries, snapshotting for state preservation and isolated multiplexing in multi-tenant clusters. Without those primitives, agentic workloads at research scale get expensive and unpredictable fast.
What GKE Agent Sandbox Delivers
The built-in SandboxWarmPool maintains pre-initialized environments so cold-start overhead is effectively eliminated. Worst-case sandbox wait times drop from up to 7.5 minutes to under 10 seconds, which matters most during large-scale parallel rollouts where thousands of sandboxes are requested simultaneously at each RL training step. Control-plane churn drops through an in-place pod recycling strategy that reuses pods across rollouts rather than tearing them down between steps. All figures are from Google Cloud’s own benchmarks; independent testing has not confirmed them.
Python SDK and Ecosystem Fit
Google Cloud shipped an RL orchestration SDK alongside the infrastructure primitive. It provides an async Python API with pluggable warm-pooling strategies and native integrations for Gymnasium, NVIDIA NeMo Gym and OpenHands. Research teams can configure agentic RL environments without touching Kubernetes YAML, keeping researchers in Python rather than debugging pod specs. For labs iterating quickly on agent architectures, that reduction in infrastructure friction is real.
How the Sandbox Market Is Splitting
Edera is taking a different angle: state preservation, restoration and cloning built directly into Kubernetes for agent execution, using microVMs for isolation below the orchestration layer.
The community-side effort is moving in the same direction. Agent Sandbox, a project under Kubernetes SIG Apps, introduces a custom resource definition called Sandbox, a lightweight, single-container environment built on Kubernetes primitives, using runtimes like gVisor or Kata Containers for isolation. It adds stable networking identities per sandbox, so distinct agents in multi-agent systems can discover and communicate without manual networking configuration.
The common thread across all three approaches is the same operational reality: long-running, stateful agent workloads do not fit the primitives Kubernetes was built for. Provisioning speed, state management and isolation depth are now infrastructure concerns for any team running agentic RL at scale. GKE Agent Sandbox addresses the provisioning and GPU-utilization side directly. How far state-management and cloning capabilities need to go will depend on how agentic RL training patterns evolve in practice.